We build AI technology with a clear purpose: eliminating operational friction. We provide the models that power decisions, the tools your team interacts with, and the autonomous workflows that keep your business moving forward without relying on manual processes.
Somos GLYNNE, una empresa especializada en desarrollo de procesos e inteligencia artificial para automatizar operaciones de negocio. Proveemos herramientas open source para integrar, reentrenar y acceder a pesos de modelos libres, democratizando el desarrollo con estas tecnologías e incentivando la investigación para crear herramientas de impacto real.
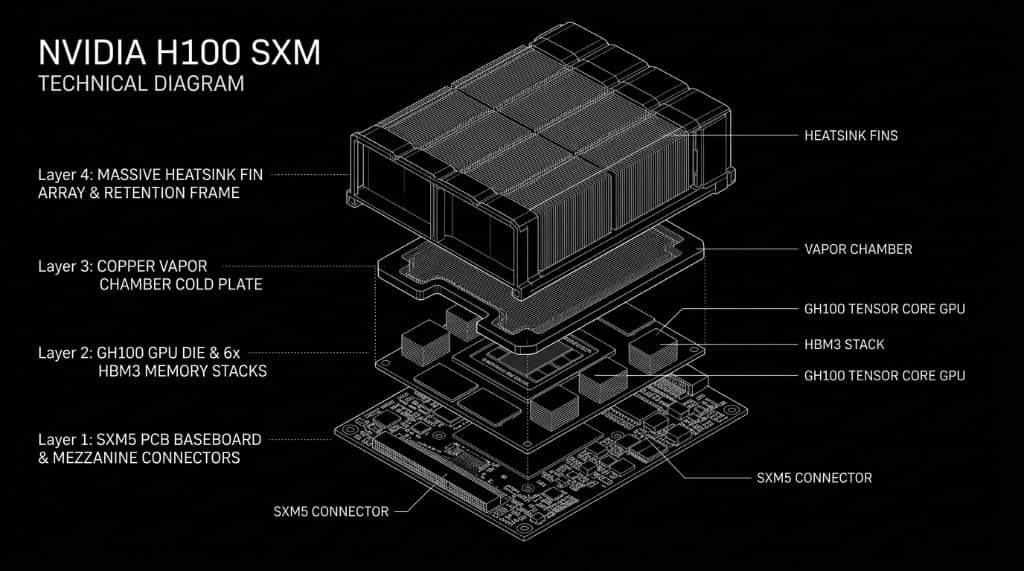
At GLYNNE, we don't rely on slow intermediaries or generic layers. Both real-time requests to our model APIs and enterprise custom Fine-Tuning workflows run directly on NVIDIA H100 SXM5 supercomputing architecture, delivering minimal latency, industrial thermal headroom, and secure data isolation.
All requests to our model APIs run accelerated by optimized inference engines (TensorRT-LLM and NVIDIA NIM), achieving ultra-low latencies down to 10ms per token in continuous streaming.
Training and parameter adaptation workloads (QLoRA) execute directly on 80GB HBM3 memory (3.35 TB/s) and FP8 Tensor Cores of GH100 silicon, adapting models to your data without bottlenecks.
GPU clusters linked point-to-point with 7x greater bandwidth than PCIe Gen 5. Enables tensor parallelism for massive models without memory fragmentation.
Your prompts, API calls, and confidential datasets are processed on hardware with cryptographic partitioning and strict zero-data-retention-at-rest policies.
Don't rely on generic responses. We possess proprietary Fine-Tuning technology (QLoRA) to train LLM models using your own manuals, databases, and operational processes. Test your model in our control panel or download the open-weight files to run it on your own infrastructure.
Upload your documents (PDF, TXT, CSV, JSON) and our technology extracts and generates hundreds of high-diversity instruction-response pairs to prevent model hallucinations and repetitive phrasing.
We inject LoRA neural adapters (r=16) into state-of-the-art base models (Llama 3.2, Qwen 2.5, Phi 3.5) quantized to 4-bit over high-performance GPU clusters.
Monitor your training process in real time. We optimize learning rates and ChatML formatting to ensure the AI strictly adheres to your corporate governance and rules.
Test your custom-trained AI immediately in our interactive chat or download the final weights (GGUF / Safetensors) to deploy on your own servers with zero per-token fees.
From specialized language models to deep reasoning architectures, we develop and adapt AI algorithms tailored to your enterprise. We perform continuous fine-tuning (QLoRA) on your own corporate data so agents resolve complex operational tasks with millimeter precision.
Explore and download our curated catalog of open-source LLM architectures. From ultra-lightweight models for local device execution to heavy foundation engines pre-configured for retraining.
Browse Full Model Library →Download ultra-fast, quantized open-source models (GGUF Q4_K_M / Q8_0) ready to run directly on consumer laptops, edge devices, or local hardware with zero token fees.
Access state-of-the-art heavy reasoning architectures (Llama 3.2, Qwen 2.5, Phi 3.5) pre-aligned for enterprise workflows and internal infrastructure deployment.
Obtain the exact mathematical algorithm file containing 100% of functional model weights with a single click. Deploy on your own private cloud or air-gapped systems.
Instantly connect any model from our open catalog directly into our QLoRA retraining panel to fine-tune parameters using your corporate operational data.
We take your enterprise to the next level by designing advanced AI pipelines. We adapt models, fine-tune algorithms with your own operational data, and deploy governed infrastructures ready to execute massive tasks with total precision and auditability.
Grab a coffee. Your first step toward innovation begins by talking with AX, the AXGLYNNE artificial intelligence. Together, you will brainstorm your bottlenecks, and AX will map out how our infrastructure and team can transform those blockers into automated systems.
Evidence of governed autonomy in production: We engineered an independent AI orchestration system for Servex—capable of processing high-volume product catalogs, resolving schema anomalies, and executing real-time ERP updates with 100% auditability.
GLYNNE is engineered by systems architects who believe AI cannot enter enterprise operations without strict deterministic control. We design the infrastructure that makes AI predictable, secure, and fully auditable.
---
system: "GLYNNE Governance Engine"
mode: "Deterministic Enforcement"
---

# SECURITY TELEMETRY

> Verifying zero-trust identity keys...
> Evaluating agent operational permissions...
> Enforcing immutable audit trail logging...

[STATUS]: System Guardrails ACTIVE & PROTECTED.
We operate on a foundation of zero-trust security and complete auditability. Review our legal frameworks, data privacy protocols, and architectural documentation, or log in to manage your dedicated enterprise AI nodes.